[ad_1]
This section discusses the experimental settings, evaluation metrics, performance of FestivalNet and its ablation study. Finally, we compare our model’s performance with SOTA models.
Experimental settings
The experimental setup utilizing the FestivalNet framework was designed to classify Rangoli patterns corresponding to five distinct Indian festivals, ensuring both high performance and strong generalization capabilities.The dataset is randomly partitioned into training, validation, and testing sets in an 80:10:10 ratio, respectively. Data augmentation techniques, including horizontal and vertical flipping, 90° rotation, and random width and height adjustments, were employed to enhance the diversity of the training dataset and improve model generalization. These augmentations effectively mimic natural variations in the data, such as different orientations and perspectives, that the model is likely to encounter in real-world scenarios. Furthermore, they help mitigate overfitting, particularly when training on a limited dataset, thereby ensuring robust performance.
The training process involved updating the FestivalNet model’s weights using the Adam optimizer, starting with an initial learning rate of 0.001. To improve convergence, the learning rate was decreased by 10% whenever the validation loss showed no improvement for five consecutive epochs. Since the task required multi-class classification, the categorical cross-entropy function was employed as the loss function. Training spanned 240 epochs with a batch size of 4, incorporating early stopping to mitigate overfitting. An Nvidia RTX 4060 GPU was utilized to enhance computational efficiency during the training phase.
Evaluation metrics
A thorough set of evaluation metrics was used to assess the effectiveness and performance of the proposed FestivalNet model in classifying Rangoli images.
Precision
Precision measures how accurately FestivalNet identifies a specific Rangoli category (denoted as cs) among the five possible categories. It is calculated as:
$${\text{Precision}}_{{\text{cs}}}=\frac{{\text{TP}}_{{\text{cs}}}}{{{\text{TP}}}_{{\text{cs}}}+{\text{FP}}_{{\text{cs}}}}.$$
(12)
Recall
Recall evaluates FestivalNet’s ability to detect all actual instances of a given Rangoli category within the predicted positive instances.It is represented as:
$${\text{Recall}}_{{\text{cs}}}=\frac{{\text{TP}}_{{\text{cs}}}}{{\text{TP}}_{{\text{cs}}}+{{\text{FN}}}_{{\text{cs}}}}.$$
(13)
F1 Score
The F1 score is a key metric for evaluating FestivalNet’s performance, particularly in cases where there is an imbalance among the Rangoli categories. It is computed as :
$${\text{F}}1{{\text{Score}}}_{{\text{cs}}}=2\times \frac{{\text{Precision}}_{{\text{cs}}}\times {{\text{Recall}}}_{{\text{cs}}}}{{\text{Precision}}_{{\text{cs}}}+{{\text{Recall}}}_{{\text{cs}}}}.$$
(14)
Accuracy
Accuracy represents the proportion of correct classifications made by the FestivalNet model. This considers both true positives (TPcs) and true negatives (TNcs), which are correctly identified as not belonging to the specific category. It is calculated as:
$${\text{Accuracy}}=\frac{{\text{TP}}_{{\text{cs}}}+{{\text{TN}}}_{{\text{cs}}}}{{\text{TP}}_{{\text{cs}}}+{{\text{TN}}}_{{\text{cs}}}+{{\text{FP}}}_{{\text{cs}}}+{\text{FN}}_{{\text{cs}}}}.$$
(15)
Confusion matrix
The confusion matrix offers a comprehensive analysis of the FestivalNet model’s performance by showing the counts of true positives (TPcs), false positives (FPcs), true negatives (TNcs), and false negatives (FNcs) for each Rangoli category.
Performance of FestivalNet
The performance of the ProposedNet model is analyzed using the confusion matrix and the ROC curve as shown in Figs. 4, 5 respectively. The confusion matrix highlights accurate classification across five classes: Diwali, Ganesh, Janmashtami, Onam, and Pongal, with the highest accuracy for Onam (96%), followed by Pongal (86%) and Janmashtami (76%), while Diwali (73%) and Ganesh (75%) show moderate performance with fewer misclassifications compared to earlier models. The ROC curve further demonstrates robust class separability, with a macro-average AUC of 0.88, indicating strong multi-class classification. Onam achieves the highest AUC (0.95), followed by Pongal (0.91), Ganesh (0.86), Janmashtami (0.85), and Diwali (0.84), showcasing ProposedNet’s improved performance and effective differentiation across all classes.

Performance metrics of FestivalNet: Confusion Matrix.

Performance metrics of FestivalNet: ROC Curve.
The Table 3 presents the performance metrics for each class using the proposed model. Precision, recall, and F1-score values are reported for classes 0 through 4. The model achieves the highest recall and F1-score in class 3, demonstrating its strong performance in that category.
Practical implications and generalizability
While FestivalNet demonstrates significant academic contributions, its practical implications are equally notable. By achieving reliable classification of Rangoli patterns, the model can be utilized in cultural heritage preservation, automated design generation for art restoration, and educational tools that promote traditional art forms. Furthermore, FestivalNet’s efficient architecture makes it suitable for deployment in real-time systems, enabling applications like virtual Rangoli design assistants or mobile apps for cultural exploration. These practical aspects underscore the model’s potential to bridge the gap between academic research and real-world utility.
Ablation study on FestivalNet
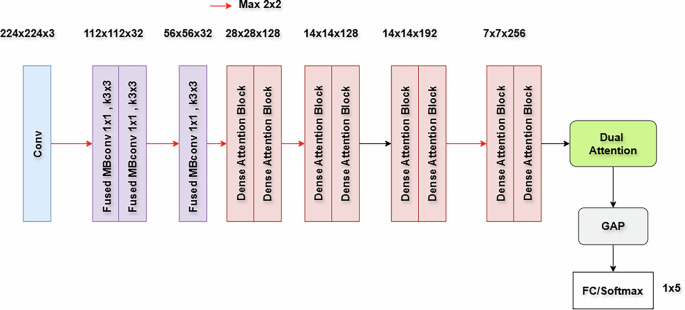
Table 4 illustrates the ablation study results evaluating the impact of Dual Attention and Fused MBConv layers on the performance of the proposed network. The configuration with both Dual Attention and Fused MBConv achieved the highest metrics, with a precision of 0.8162, recall of 0.8107, F1-score of 0.8115, and accuracy of 0.8158, highlighting the complementary benefits of these components. Removing Fused MBConv while retaining Dual Attention resulted in a significant drop in performance, demonstrating the importance of Fused MBConv for feature extraction. Conversely, disabling Dual Attention while keeping Fused MBConv led to moderately reduced but still competitive performance, indicating the standalone utility of Fused MBConv. These results emphasize the synergistic contribution of Dual Attention and Fused MBConv layers in improving network performance.
Removing Fused MBConv (Dual Attention only) causes a drastic drop: Precision falls by 14% to 0.6984, Recall to 0.6899, F1 to 0.6829, Accuracy to 0.6908. This sharp decline highlights Fused MBConv’s central role in extracting discriminative features. Disabling Dual Attention (Fused MBConv only) results in milder reductions—Precision = 0.8022, Recall = 0.7937, F1-Score = 0.7949, Accuracy = 0.7993—demonstrating that Fused MBConv independently offers strong representation, while Dual Attention contributes valuable refinement. The full model’s superior performance indicates a synergistic effect: the Fused MBConv module builds a robust foundation of feature extraction, while the Dual Attention mechanism selectively enhances relevant spatial and channel contexts. These findings confirm that FestivalNet is best optimized through deliberate integration of both modules.
Comparative experiments
EfficientNetV2B033(Fig. 6) demonstrates strong multi-class classification performance, as illustrated by the confusion matrix and ROC curve. The confusion matrix reveals high accuracy for Onam (96%) and Pongal (98%), with moderate performance for Janmashtami (73%), Diwali (64%), and Ganesh (62%), where the latter classes experience higher misclassifications. The ROC curve highlights the model’s robust class separability, achieving a macro-average AUC of 0.87. Pongal and Onam stand out with the highest AUCs of 0.97 and 0.94, respectively, followed by Janmashtami (0.84), while Ganesh (0.78) and Diwali (0.79) show relatively lower AUCs. These results demonstrate that EfficientNetV2B0 excels in identifying specific classes, such as Onam and Pongal, while maintaining consistent overall classification performance.

Performance Comparison of related CNN models: Confusion Matrix and ROC Curve.
Table 5 presents the performance metrics for each class using the EfficientNetV2B0 model, highlighting precision, recall, and F1-score. Class 4 achieves the highest performance with a precision of 0.8333, recall of 0.9821, and an F1-score of 0.9016, demonstrating excellent classification accuracy. Similarly, Class 3 performs strongly with an F1-score of 0.8758, supported by a recall of 0.9571 and precision of 0.8072. Class 2 exhibits balanced performance with an F1-score of 0.7541, recall of 0.7302, and precision of 0.7797. In contrast, Class 0 and Class 1 show relatively lower performance, with F1-scores of 0.6863 and 0.6789, respectively, reflecting challenges in distinguishing these classes. Overall, the metrics indicate that EfficientNetV2B0 delivers robust classification performance, particularly for Classes 3 and 4, while leaving room for improvement in Classes 0 and 1.
The performance of MobileNet (Fig. 6) is illustrated through the confusion matrix and ROC curve, demonstrating strong multi-class classification capabilities across five classes: Diwali, Ganesh, Janmashtami, Onam, and Pongal. The confusion matrix shows high accuracy for Onam (93%) and Pongal (93%), moderate performance for Diwali (69%) and Ganesh (68%), and relatively lower accuracy for Janmashtami (68%) due to notable misclassifications. The ROC curve highlights excellent class separability, with a macro-average AUC of 0.86. Pongal achieves the highest AUC (0.95), followed by Onam (0.94), Ganesh (0.82), and Janmashtami (0.81), while Diwali has the lowest AUC (0.80). These results reflect MobileNet’s consistent performance, with particular strengths in identifying Onam and Pongal.
The Table 6 shows the performance metrics for each class using the MobileNet35 model. Precision, recall, and F1-score values are provided for classes 0 through 4, with class 4 achieving the highest F1-score. The model performs particularly well in recall and F1-score for class 4, demonstrating strong overall performance.
The performance of MobileNetV3Small (Fig. 6) is evaluated using a confusion matrix and ROC curve, demonstrating consistent classification across five classes: Diwali, Ganesh, Janmashtami, Onam, and Pongal. The confusion matrix reveals strong accuracy for the Onam class (91%) and Pongal (88%), with moderate performance for Diwali (67%), Ganesh (60%), and Janmashtami (75%), indicating occasional misclassifications. The ROC curve highlights robust class separability, achieving a macro-average AUC of 0.85. Onam and Pongal exhibit the highest AUCs (0.92 and 0.91, respectively), while Diwali (0.81), Janmashtami (0.84), and Ganesh (0.78) show satisfactory discrimination. Overall, MobileNetV3Small delivers reliable multi-class classification with a focus on strong separability for key classes.
The Table 7 presents the performance metrics for each class using the MobileNetV3 Small model35. Class 2 achieves the highest F1-score, with a balanced precision and recall of 0.7460. The model performs well across all classes, with class 3 having the best recall and F1-score.
The Table 8 shows the performance metrics for each class using the MobileNetV3 Large model35. Class 4 exhibits the highest performance across all metrics with a precision, recall, and F1-score of 0.9107, demonstrating its strong detection capabilities. Classes 0 and 3 also perform well, with precision and recall scores close to 0.80, while Class 2 shows relatively lower performance, especially in recall. The performance of MobileNetV3Large (Fig. 7) is visualized through the confusion matrix and ROC curve, highlighting robust classification capabilities across five classes: Diwali, Ganesh, Janmashtami, Onam, and Pongal. The confusion matrix reveals strong accuracy for Pongal (91%) and Onam (90%), with moderate performance for Diwali (78%) and Ganesh (68%), while Janmashtami exhibits relatively lower accuracy (60%) due to higher misclassifications. The ROC curve demonstrates excellent class separability, with a macro-average AUC of 0.86. Pongal achieves the highest AUC (0.95), followed by Onam (0.92), Diwali (0.85), and Ganesh (0.81), while Janmashtami has the lowest AUC (0.77), aligning with its classification challenges. Overall, MobileNetV3Large delivers strong performance, particularly for Pongal and Onam, with consistent multi-class classification effectiveness Fig. 8.

Performance Comparison of related CNN models: Confusion Matrix and ROC Curve.

Comparison of Class Activation Maps across Models for Festive Images.
The performance of the SwinTransformerV2Base model with a window size of 8 is visualized through the confusion matrix (Fig. 7) and the Receiver Operating Characteristic (ROC) curve (Fig. 7). The confusion matrix highlights the classification performance across five classes: Diwali, Ganesh, Janmashtami, Onam, and Pongal, with diagonal entries representing correct predictions and off-diagonal elements indicating misclassifications. The model demonstrates strong performance for the Onam class, achieving 87% accuracy, while moderate accuracies are observed for Pongal (64%) and Diwali (55%), though these classes exhibit some misclassifications, particularly with Ganesh and Janmashtami. Lower accuracies for Ganesh and Janmashtami reflect challenges in distinguishing these classes, as evident from notable off-diagonal values. The ROC curve further evaluates the model’s discriminative ability, with the highest area under the curve (AUC) for the Onam class (0.90), indicating strong separability. Moderate AUC scores for Pongal (0.77) and Diwali (0.73) reflect satisfactory performance, while the Ganesh and Janmashtami classes exhibit the lowest AUC values of 0.71 and 0.73, respectively, aligning with their lower classification accuracies. The macro-average AUC of 0.77 highlights the model’s overall ability to perform multi-class classification, with notable strengths and areas for improvement Fig. 9.

Samples of misclassification results.
Table 9 provides the performance results of the model across different classes. The results indicate variability in the model’s effectiveness. For instance, the model achieved the highest F1-score (0.824) for Class 3, with corresponding precision and recall values of 0.782 and 0.871, respectively. Conversely, Class 1 recorded the lowest F1-score (0.528), which highlights potential challenges in accurately classifying instances in this category. Classes 0, 2, and 4 showed moderate performance, with F1-scores ranging from 0.561 to 0.621.
Table 10 presents the performance metrics of various models, including the proposed method, based on Precision, Recall, F1-Score, and Accuracy. The proposed method achieves the highest overall performance, with an F1-Score of 0.8115 and an Accuracy of 0.8158, outperforming all baseline models. Among the baselines, the v2_b0 and Mobilenet variants show relatively competitive performance, with F1-Scores ranging from 0.7793 to 0.7731. In contrast, DenseNet and Inception-ResNet-v236 models exhibit lower scores across all metrics, underscoring their suboptimal performance for the given task. These results highlight the superior predictive capabilities of the proposed method.The models compared in Table 10 were chosen to represent a diverse and relevant cross-section of the state-of-the-art in image classification as of 2025. EfficientNetV2 was included due to its demonstrated superior training speed and parameter efficiency, delivering strong classification performance with up to 6.8 × better parameter efficiency and significantly faster training than prior ConvNets on datasets like ImageNet, CIFAR, and others. MobileNet variants (V2, V3 large/small) offer widely recognized benchmarks for mobile and edge deployment due to their compact size, low latency, and optimized inference on resource-constrained devices. Additionally, Swin Transformer represents the forefront of vision transformer architectures, achieving strong hierarchical modeling and SOTA performance across classification, detection, and segmentation benchmarks while maintaining linear computational complexity relative to image size. By including these alongside classical CNN backbones such as DenseNet and Inception-ResNet, our comparison spans both efficient edge-optimized models and cutting-edge transformer-based models—enabling a comprehensive and fair evaluation of our proposed network across performance, architectural paradigms, and deployment contexts. While FestivalNet achieves superior classification performance, its efficiency in terms of parameter count, model size, and inference speed must be contextualized—especially against lightweight architectures. For instance, SqueezeNet attains AlexNet-level accuracy with approximately 50 × fewer parameters and a sub-0.5 MB model size.
The visual analysis of Class Activation Maps between the proposed model and baseline architectures highlights significant variations in feature focus and attention distribution. The Proposed Net demonstrates focused activations on semantically significant regions, such as highlighting the central diya in Diwali images and attending to the deity’s face and trunk in Ganesh images, indicating precise localization of class-relevant features. In contrast, EfficientV2_b0 exhibits broader activations, capturing key areas like the central motifs in Diwali and Onam, but also focusing on peripheral regions, reflecting a lack of spatial precision. Mobilenet shows consistent attention on prominent features; however, its activations are diffused, as seen in the Janmashtami image where activations highlight the peacock feather but spread into surrounding areas. MobilenetV3Large highlights essential components, such as the diya in Diwali and the trunk in Ganesh, but its attention is moderately dispersed, occasionally including irrelevant regions. MobilenetV3Small focuses more on localized features, as observed in the Pongal image where activations are concentrated on decorated pots, though some spillover into the background persists. FestivalNet exhibits superior localization of class-relevant features, focusing on key motifs like central designs and symmetrical patterns. EfficientNetV2b0 and MobileNet show broader, less focused activations, often capturing irrelevant regions, thereby impacting their precision in handling subtle inter-class differences. In summary, the Proposed Net achieves superior feature localization, focusing on class-relevant regions with higher precision, while baseline models exhibit varying levels of activation dispersion.
Limitations and future work
Misclassification in the FestivalNet model indicates the challenges associated with distinguishing intricate patterns in Rangoli designs. Certain Rangoli designs share common features across festivals, such as floral elements, circular arrangements, or the use of similar colors. Rangoli styles vary by region and may blend motifs from multiple festivals. For example, a design classified under Diwali could have elements resembling Ganesh Chaturthi, leading to confusion. While FestivalNet performs well, its architecture might have limitations in capturing fine-grained details or recognizing subtle differences in complex designs. This could particularly affect cases where the dataset contains overlapping or ambiguous features. This work makes significant contributions to cultural heritage preservation by offering a scalable framework for digitizing, analyzing, and archiving intricate art forms like Rangoli. Beyond its immediate application, FestivalNet has the potential to influence other areas of AI and cultural heritage preservation. For instance, the methods proposed in this study could be adapted to classify and analyze other traditional art forms, such as Mandalas, Alpana, and Kolam, fostering global recognition and preservation of diverse artistic traditions. The integration of class activation maps also provides a means for detailed documentation, enabling deeper insights into patterns and motifs that carry cultural significance.
Future directions include extending the dataset to encompass international variations of Rangoli and similar traditional art forms, thereby enhancing the model’s generalizability across cultural boundaries. Additionally, the deployment of real-time classification systems could revolutionize interactive experiences, such as virtual reality (VR) and augmented reality (AR) platforms, allowing users to explore and create digital representations of traditional art. These advancements could also support educational initiatives, making cultural heritage more accessible to younger generations and global audiences.
Moreover, integrating FestivalNet with smart IoT devices could enable automated Rangoli generation systems for festive or ceremonial events, blending tradition with technology. Further research could explore collaborative efforts with artists and cultural organizations to develop hybrid systems that preserve and innovate upon traditional art forms, ensuring their relevance and continuity in the digital age.
[ad_2]
Source link